litellm

Vendor: BerriAI

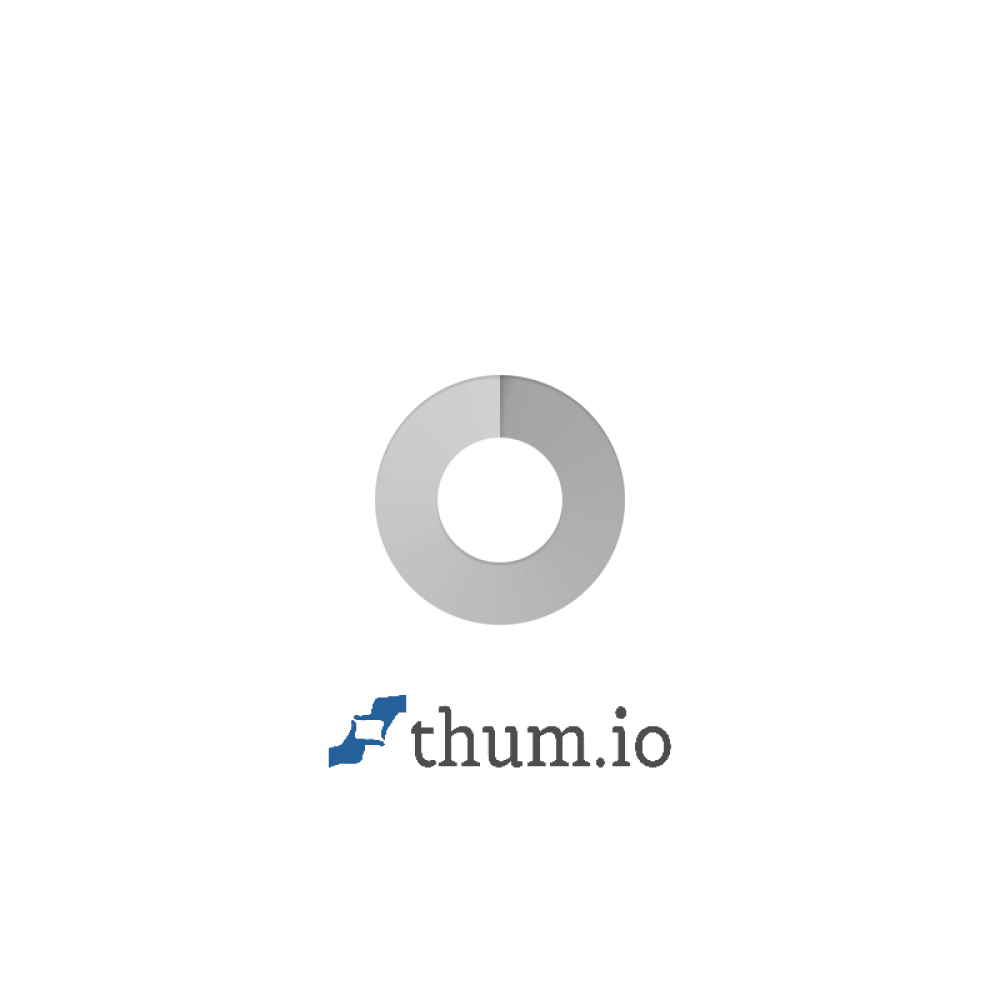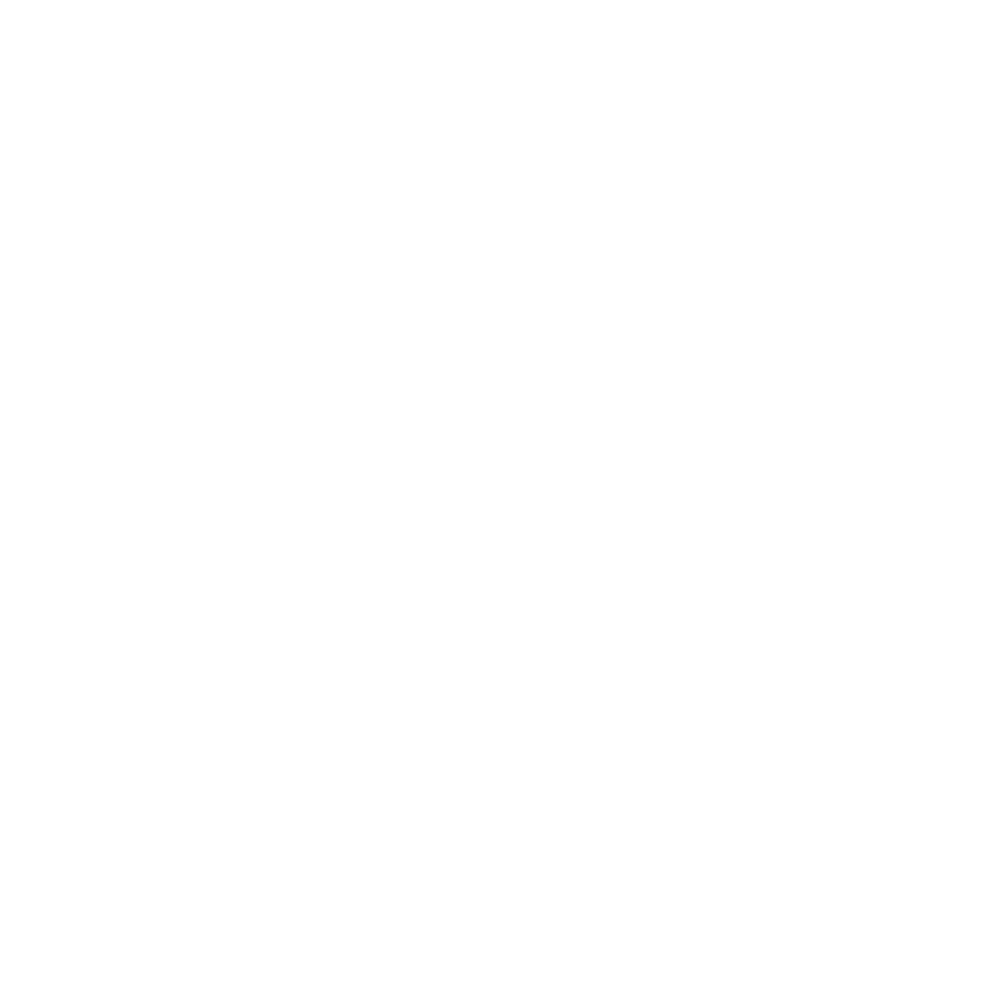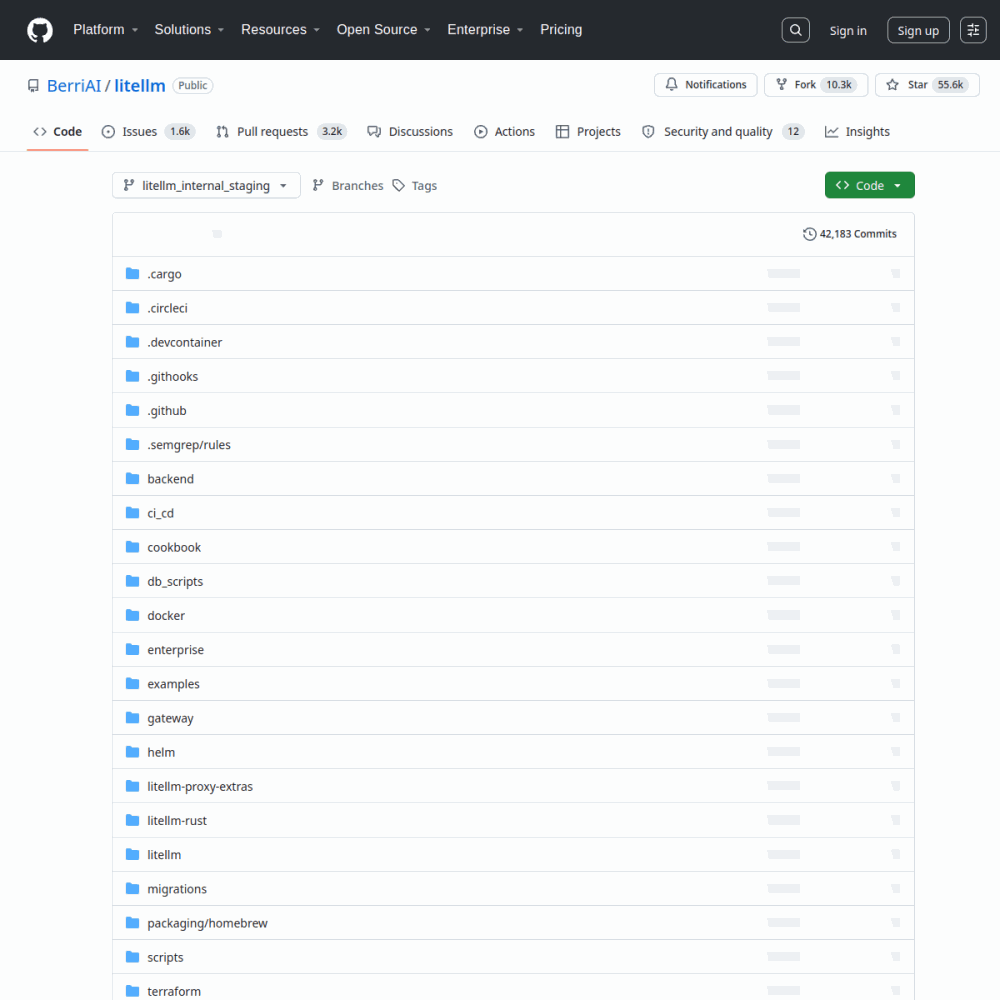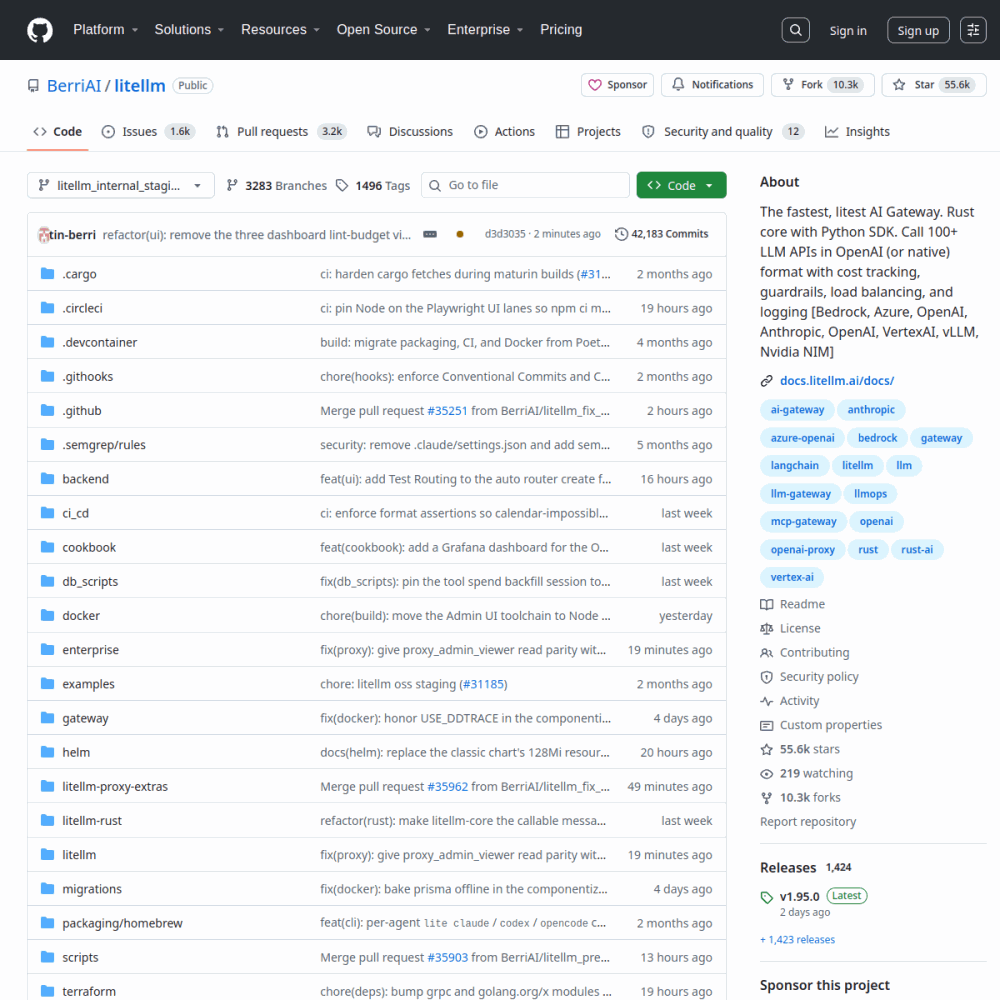
The fastest, litest AI Gateway. Rust core with Python SDK. Call 100+ LLM APIs in OpenAI (or native) format with cost tracking, guardrails, load balancing, and logging [Bedrock, Azure, OpenAI, Anthropic, OpenAI, VertexAI, vLLM, Nvidia NIM]

View Repository

Official Preview
litellm

Technical Specifications

RepositoryBerriAI/litellm
GitHub Stars★ 57.2k
Forks10.9k forks
Primary LanguagePython
LicenseNOASSERTION
Technical DomainAGENTS
ai-gatewayanthropicazure-openaibedrockgatewaylangchainlitellmllmllm-gatewayllmopsmcp-gatewayopenaiopenai-proxyrustrust-aivertex-ai
4.0Overall
Functionality
4.0
Documentation
4.0
Activity
4.0
Ease of use
4.0

Quickstart & Installation

$ git clone https://github.com/BerriAI/litellm.git && cd litellm

Comprehensive Review

<h1 align="center">
🚅 LiteLLM
</h1>
<p align="center">
<p align="center">LiteLLM AI Gateway
</p>
<p align="center">Open Source AI Gateway for 100+ LLMs. Self-hosted. Enterprise-ready. Call any LLM in OpenAI format.</p>
<p align="center">
<a href="https://render.com/deploy?repo=https://github.com/BerriAI/litellm" target="_blank" rel="nofollow"><img src="https://render.com/images/deploy-to-render-button.svg" alt="Deploy to Render" height="40"

Project Background

LiteLLM was developed by BerriAI to address the fragmentation in the large language model landscape. The project aims to simplify integration by allowing developers to call over 100 different LLM APIs using a standardized OpenAI-compatible format.

The architecture combines a Rust core for performance with a Python SDK for flexibility. This design choice supports the goal of creating a lightweight yet fast AI gateway capable of handling diverse provider endpoints efficiently. The project claims to be the fastest and lightest option available in the current market.

Core Use Cases

Teams building multi-model applications use LiteLLM to abstract away provider-specific SDKs. This allows engineers to switch between providers like Anthropic, Azure OpenAI, and Bedrock without rewriting core logic.

Operations teams leverage the built-in cost tracking and logging features to monitor usage across various endpoints. The gateway also supports guardrails and load balancing, making it suitable for managing production traffic and ensuring compliance. Supported providers include VertexAI, vLLM, and Nvidia NIM alongside major cloud platforms.

Developers integrating with LangChain or similar frameworks benefit from the unified interface. This reduces the complexity of managing multiple API keys and configuration settings across different AI services.

Quickstart Guide

Installation is straightforward via Python package managers. Users can add the library to their environment using pip, ensuring access to the Python SDK and underlying Rust components.

Once installed, developers can initialize the gateway and configure provider credentials through environment variables. The system supports self-hosted deployments or cloud options like Render for immediate availability.

Basic usage involves importing the library and making calls in the standard OpenAI format. This minimal setup allows for rapid prototyping before scaling to enterprise-grade configurations. Users can also opt for native API formats if specific provider features are required.

Practicality Assessment

The project holds a strong rating of 4.0 out of 5 across functionality, documentation, activity, and ease of use. This indicates a mature codebase with reliable performance and accessible resources for new users.

While described as enterprise-ready, the license status is listed as NOASSERTION, which requires legal review for commercial deployment. Users should verify licensing terms before integrating into proprietary systems to avoid compliance issues. The consistent 4.0 rating across all categories suggests stability for production environments.

Real-world Deployments

Integration scenarios often involve middleware layers for applications requiring dynamic model selection. The support for MCP-gateway and LangChain suggests compatibility with broader AI development ecosystems.

Organizations seeking self-hosted solutions utilize the gateway to maintain control over data privacy and model access. The ability to proxy requests to Nvidia NIM or VertexAI allows for hybrid cloud strategies without vendor lock-in. This setup is particularly useful for teams needing to balance cost and performance across multiple infrastructure providers.

Core Strengths

    Considerations & Limitations

    • Requires appropriate GPU memory planning and concurrency tuning for production.

    Frequently Asked Questions (FAQ)

    What is litellm and what key challenges does it solve?

    litellm is an open-source AI project developed primarily in Python under the NOASSERTION license. The fastest, litest AI Gateway. Rust core with Python SDK. Call 100+ LLM APIs in OpenAI (or native) format with cost tracking, guardrails, load balancing, and logging [Bedrock, Azure, OpenAI, Anthropic, OpenAI, VertexAI, vLLM, Nvidia NIM]. LiteLLM was developed by BerriAI to address the fragmentation in the large language model landscape. The project aims to simplify integration by allowing developers to call over 100 different LLM APIs using a standardized OpenAI-compatible format. The architecture combines a Rust core for performance with a Python SDK for flexibility. This design choice supports the goal of creating a lightweight yet fast AI gateway capable of handling diverse provider endpoints efficiently. The project claims to be the fastest and lightest option available in the current market.

    How can I quickly install and run litellm locally?

    Installation is straightforward via Python package managers. Users can add the library to their environment using pip, ensuring access to the Python SDK and underlying Rust components. Once installed, developers can initialize the gateway and configure provider credentials through environment variables. The system supports self-hosted deployments or cloud options like Render for immediate availability. Basic usage involves importing the library and making calls in the standard OpenAI format. This minimal setup allows for rapid prototyping before scaling to enterprise-grade configurations. Users can also opt for native API formats if specific provider features are required.

    What are the main use cases and strengths of litellm?

    litellm is well-suited for . With an overall rating of 4.0/5, it offers strong community activity, reliable performance, and easy integration with existing AI pipelines.

    What limitations or architectural considerations should be kept in mind for litellm?

    The project holds a strong rating of 4.0 out of 5 across functionality, documentation, activity, and ease of use. This indicates a mature codebase with reliable performance and accessible resources for new users. While described as enterprise-ready, the license status is listed as NOASSERTION, which requires legal review for commercial deployment. Users should verify licensing terms before integrating into proprietary systems to avoid compliance issues. The consistent 4.0 rating across all categories suggests stability for production environments.