Chatbot Arena 中文
Crowdsourced open LLM benchmark leaderboard for Chinese language
Official Preview
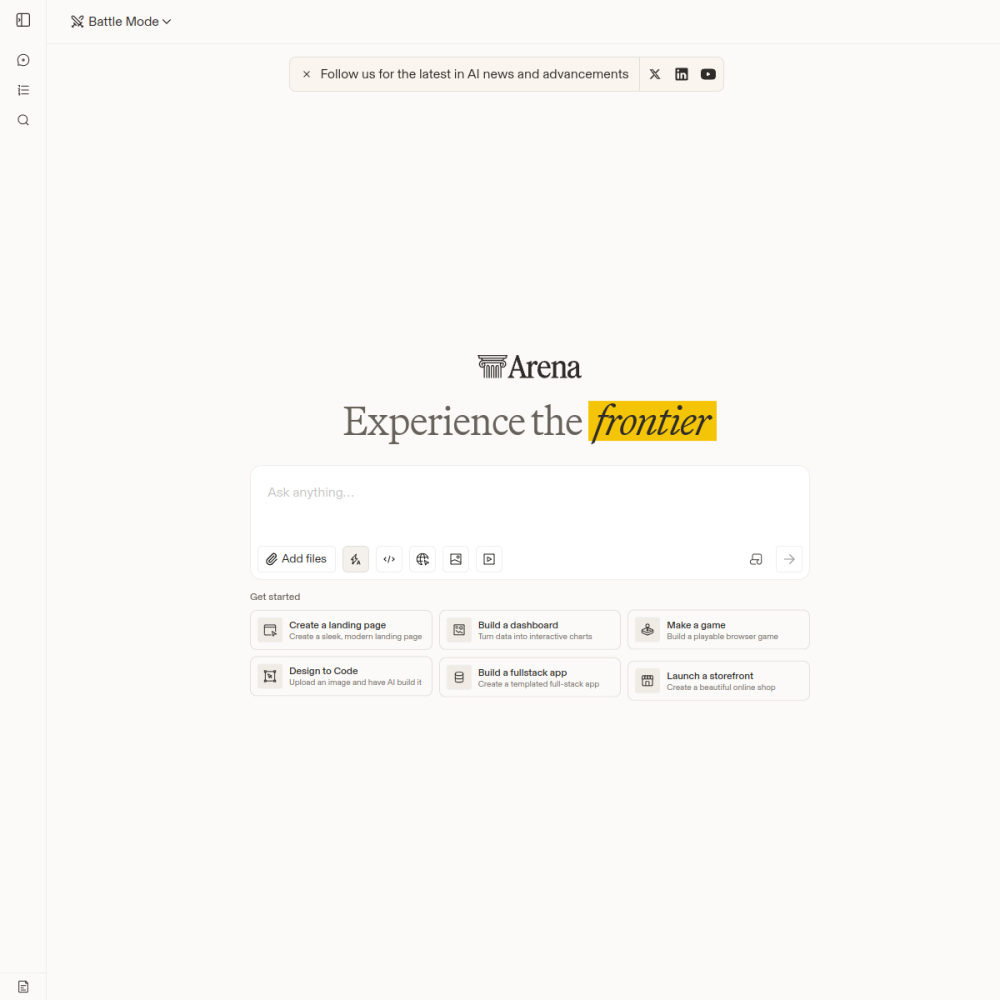
Crowdsourced open LLM benchmark leaderboard for Chinese language
In-Depth Review
Chatbot Arena 中文 is a crowdsourced benchmark platform that ranks large language models specifically on their Chinese-language performance. Unlike closed evaluations, it relies on real user votes to determine which models produce the most helpful, accurate, and natural responses in Chinese.
The platform operates through a blind comparison format: users submit prompts, receive responses from two anonymous models, and vote on which one is better. Over time, these votes build an Elo-style ranking that reflects community consensus on model quality.
Chatbot Arena 中文 is the Chinese-language edition of the LMArena benchmarking system. It provides a transparent, community-driven leaderboard where large language models are evaluated head-to-head on Chinese prompts.
The methodology mirrors the original Chatbot Arena: models are paired randomly, users vote without knowing which model is which, and an Elo rating system aggregates results into a ranked list. This approach avoids the biases of single-question benchmarks and gives a more holistic view of model capability.
The platform offers blind A/B model comparisons, an Elo-based ranking system, and real-time leaderboard updates. Users can submit prompts in Chinese and vote on response quality across dimensions like accuracy, fluency, and helpfulness.
Because the benchmark is open and crowdsourced, anyone can participate without registration barriers. The leaderboard is publicly accessible, making it easy to track how different models perform over time.
Chatbot Arena 中文 serves researchers, developers, and organizations evaluating LLM performance for Chinese-language applications. It is particularly useful for teams selecting models for customer service, content generation, or translation tasks in Chinese markets.
General users interested in AI capabilities can also use the platform to compare models interactively and understand which systems handle Chinese language tasks most effectively.
Teams building Chinese-language AI products use the leaderboard to shortlist models before committing to a vendor. Researchers cite the rankings when comparing model architectures or training approaches.
Content creators and marketers reference the benchmark to choose models that produce natural-sounding Chinese copy. Educators and students use it to explore how different models handle nuanced language tasks.
Visit lmarena.ai to access the platform. Select the Chinese language mode, enter a prompt, and compare responses from two anonymous models. Vote on the better response to contribute to the leaderboard.
For meaningful results, use diverse prompts covering different domains—technical, creative, conversational. Multiple votes from varied users strengthen the reliability of the rankings. Check the leaderboard regularly to see how model positions shift as new data accumulates.
Yes. The platform is open and crowdsourced. Users can submit prompts and vote on model responses without paying or creating an account.
Models are ranked using an Elo rating system based on pairwise user votes. Each comparison contributes to a model's score, and the leaderboard updates as more votes are collected.
The platform primarily evaluates publicly available models. For submission inquiries, check the official website at lmarena.ai for current participation guidelines.
HF open LLM leaderboard
Independent AI model speed & quality evals
Contamination-free coding benchmark
AI model battle & evaluation platform