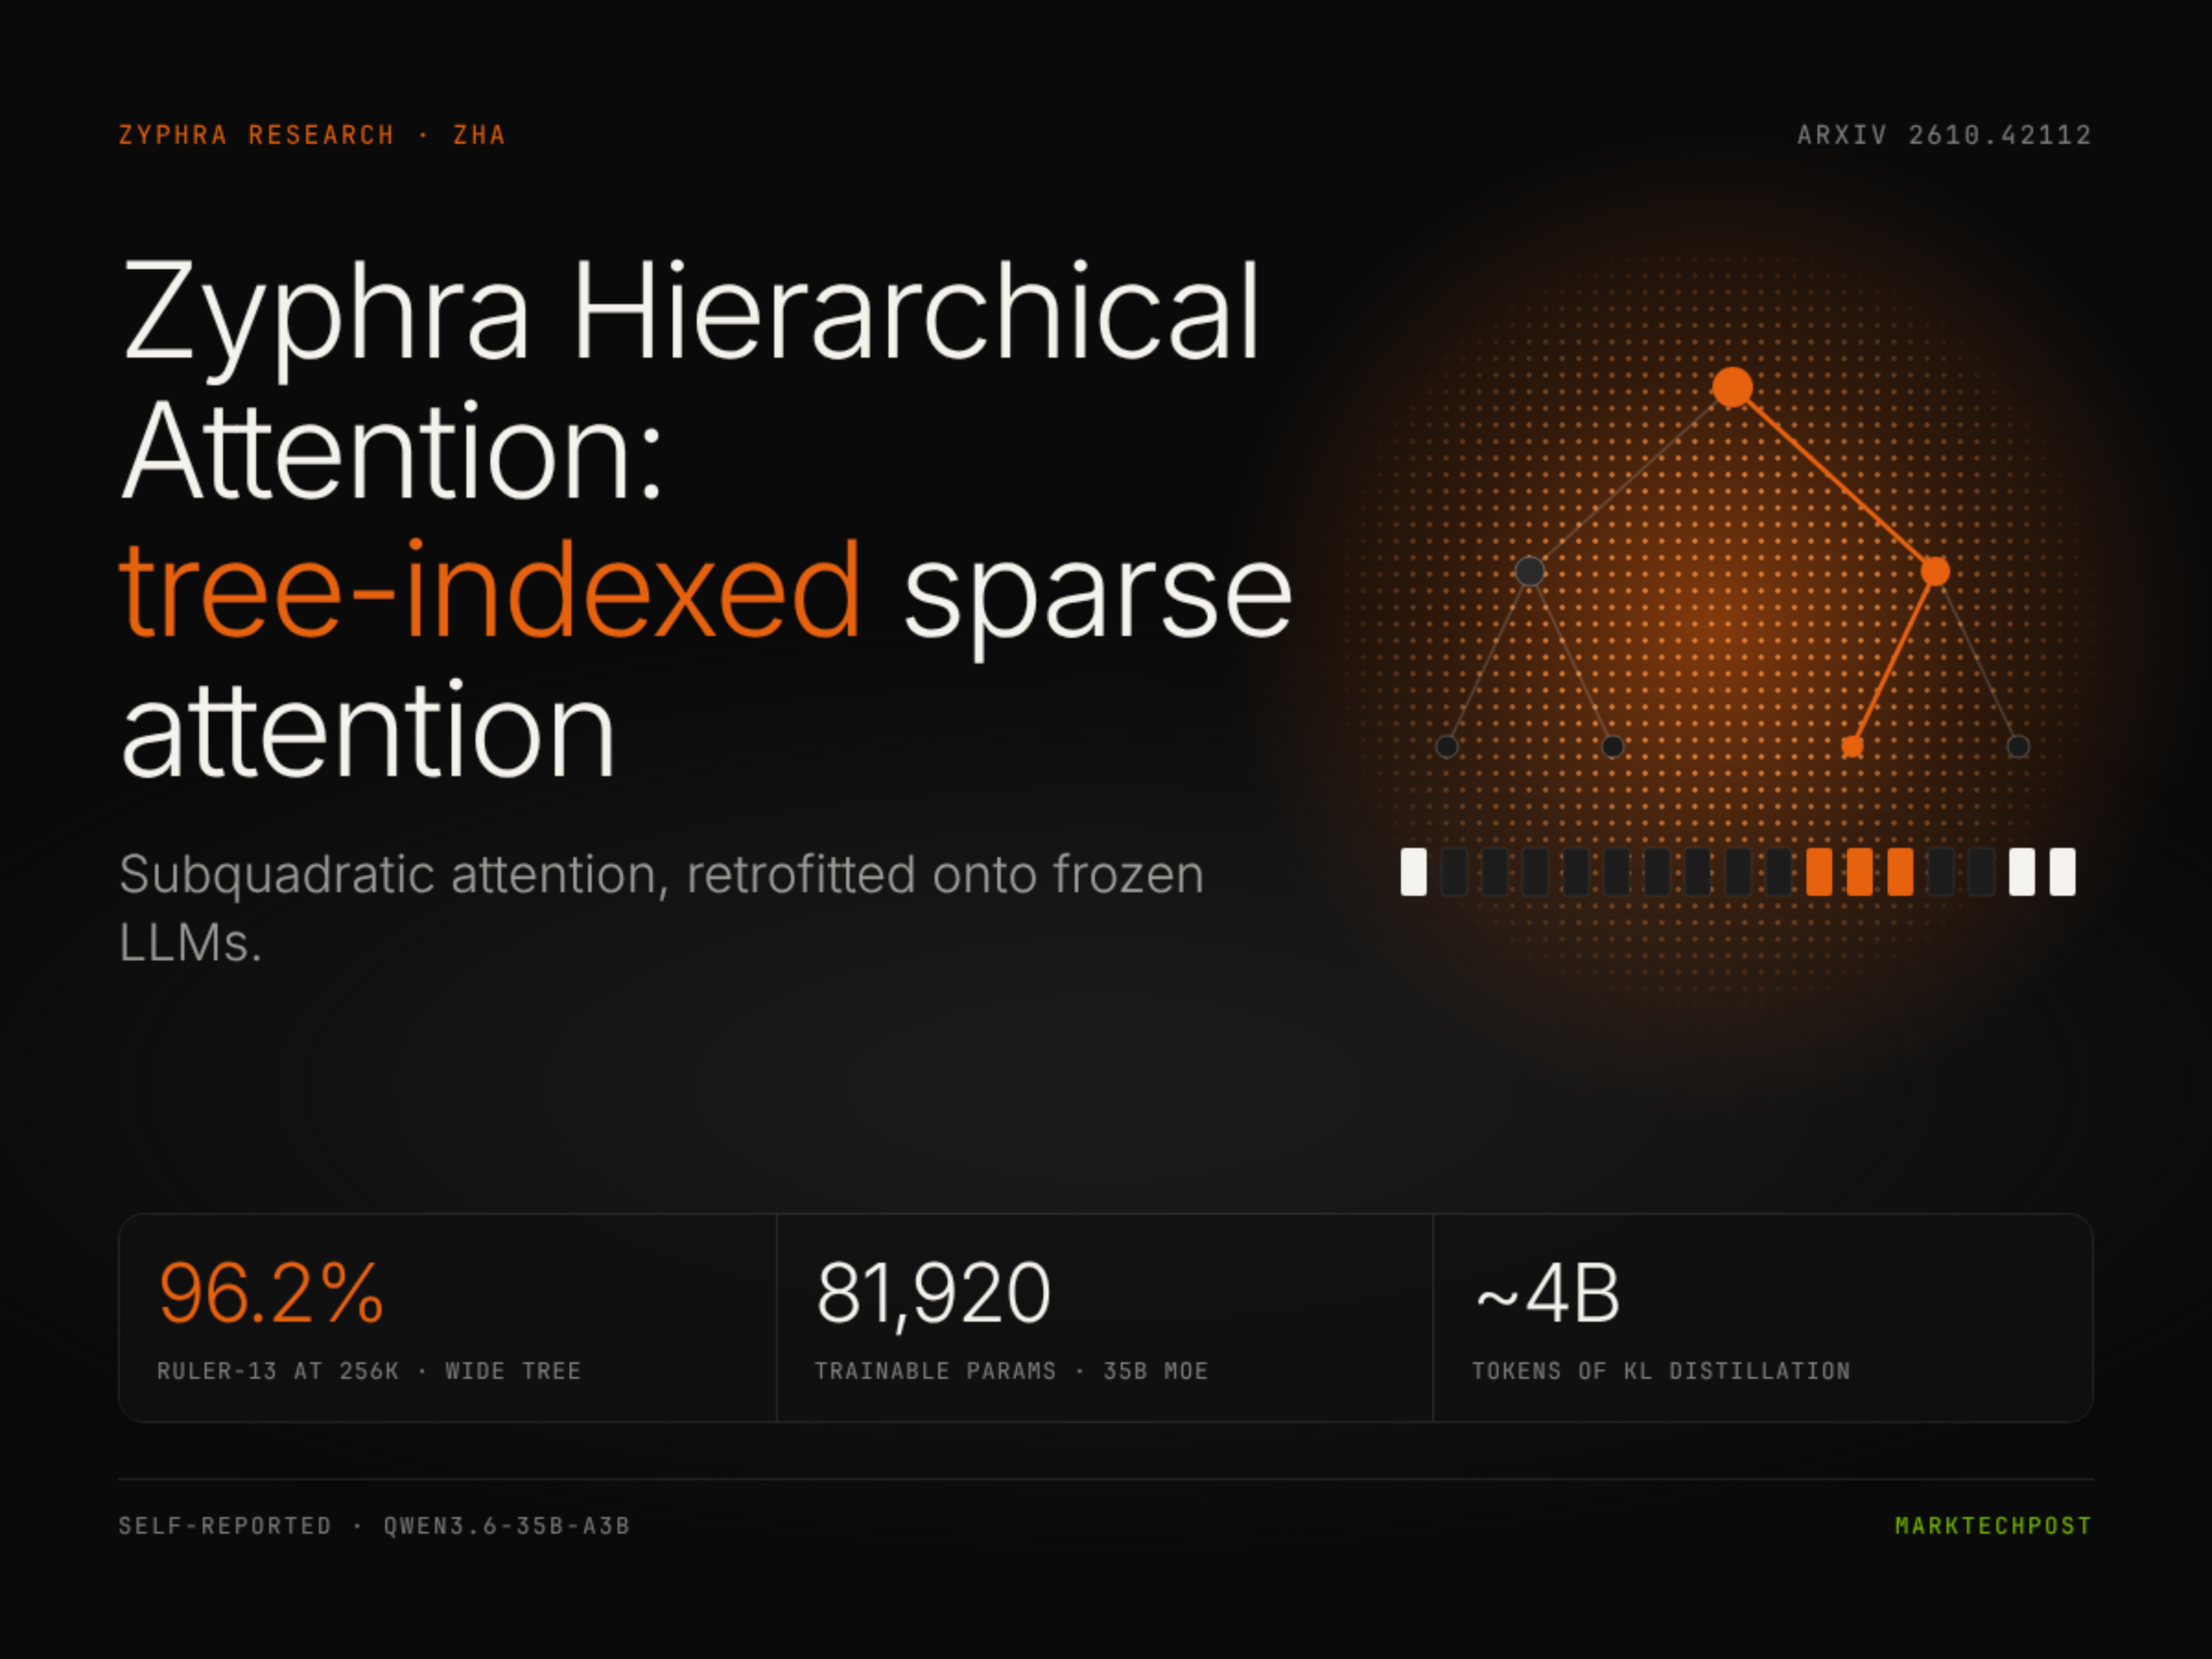
Zyphra AI Introduces Zyphra Hierarchical Attention (ZHA): A Path to True Subquadratic Attention
Zyphra AI introduces Zyphra Hierarchical Attention (ZHA), a tree-indexed sparse attention method that retrofits frozen LLMs via 4B tokens of distillation, matching dense attention on reasoning and 256K retrieval benchmarks.
Key Takeaways
- Key Highlight:Zyphra AI introduces Zyphra Hierarchical Attention (ZHA), a tree-indexed sparse attention method that retrofits frozen LLMs via 4B tokens of distillation, matching dense attention on reasoning and 256K retrieval benchmarks.
- Key Topics:Zyphra, AI, Introduces, Hierarchical
Zyphra AI has introduced Zyphra Hierarchical Attention (ZHA), a new attention mechanism designed to achieve subquadratic scaling. It uses a tree-indexed sparse pattern that limits the number of token pairs each query attends to, reducing computational complexity compared to standard dense attention.
The method retrofits frozen large language models through distillation with 4B tokens, meaning it can be applied to existing models without retraining from scratch. According to the source, ZHA matches dense attention performance on reasoning benchmarks and on retrieval tasks with a 256K context length.
This matters because attention is a major bottleneck for long sequences. Subquadratic approaches could lower inference cost and memory usage, and the ability to retrofit frozen models avoids the expense of full retraining.
The likely impact is more efficient long-context processing in existing LLMs, though broader validation across diverse tasks and model sizes would be needed to confirm general applicability.
This page provides an editorial summary based on publicly available information. It is not a republished article. Use the source link below for the original report.