Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass
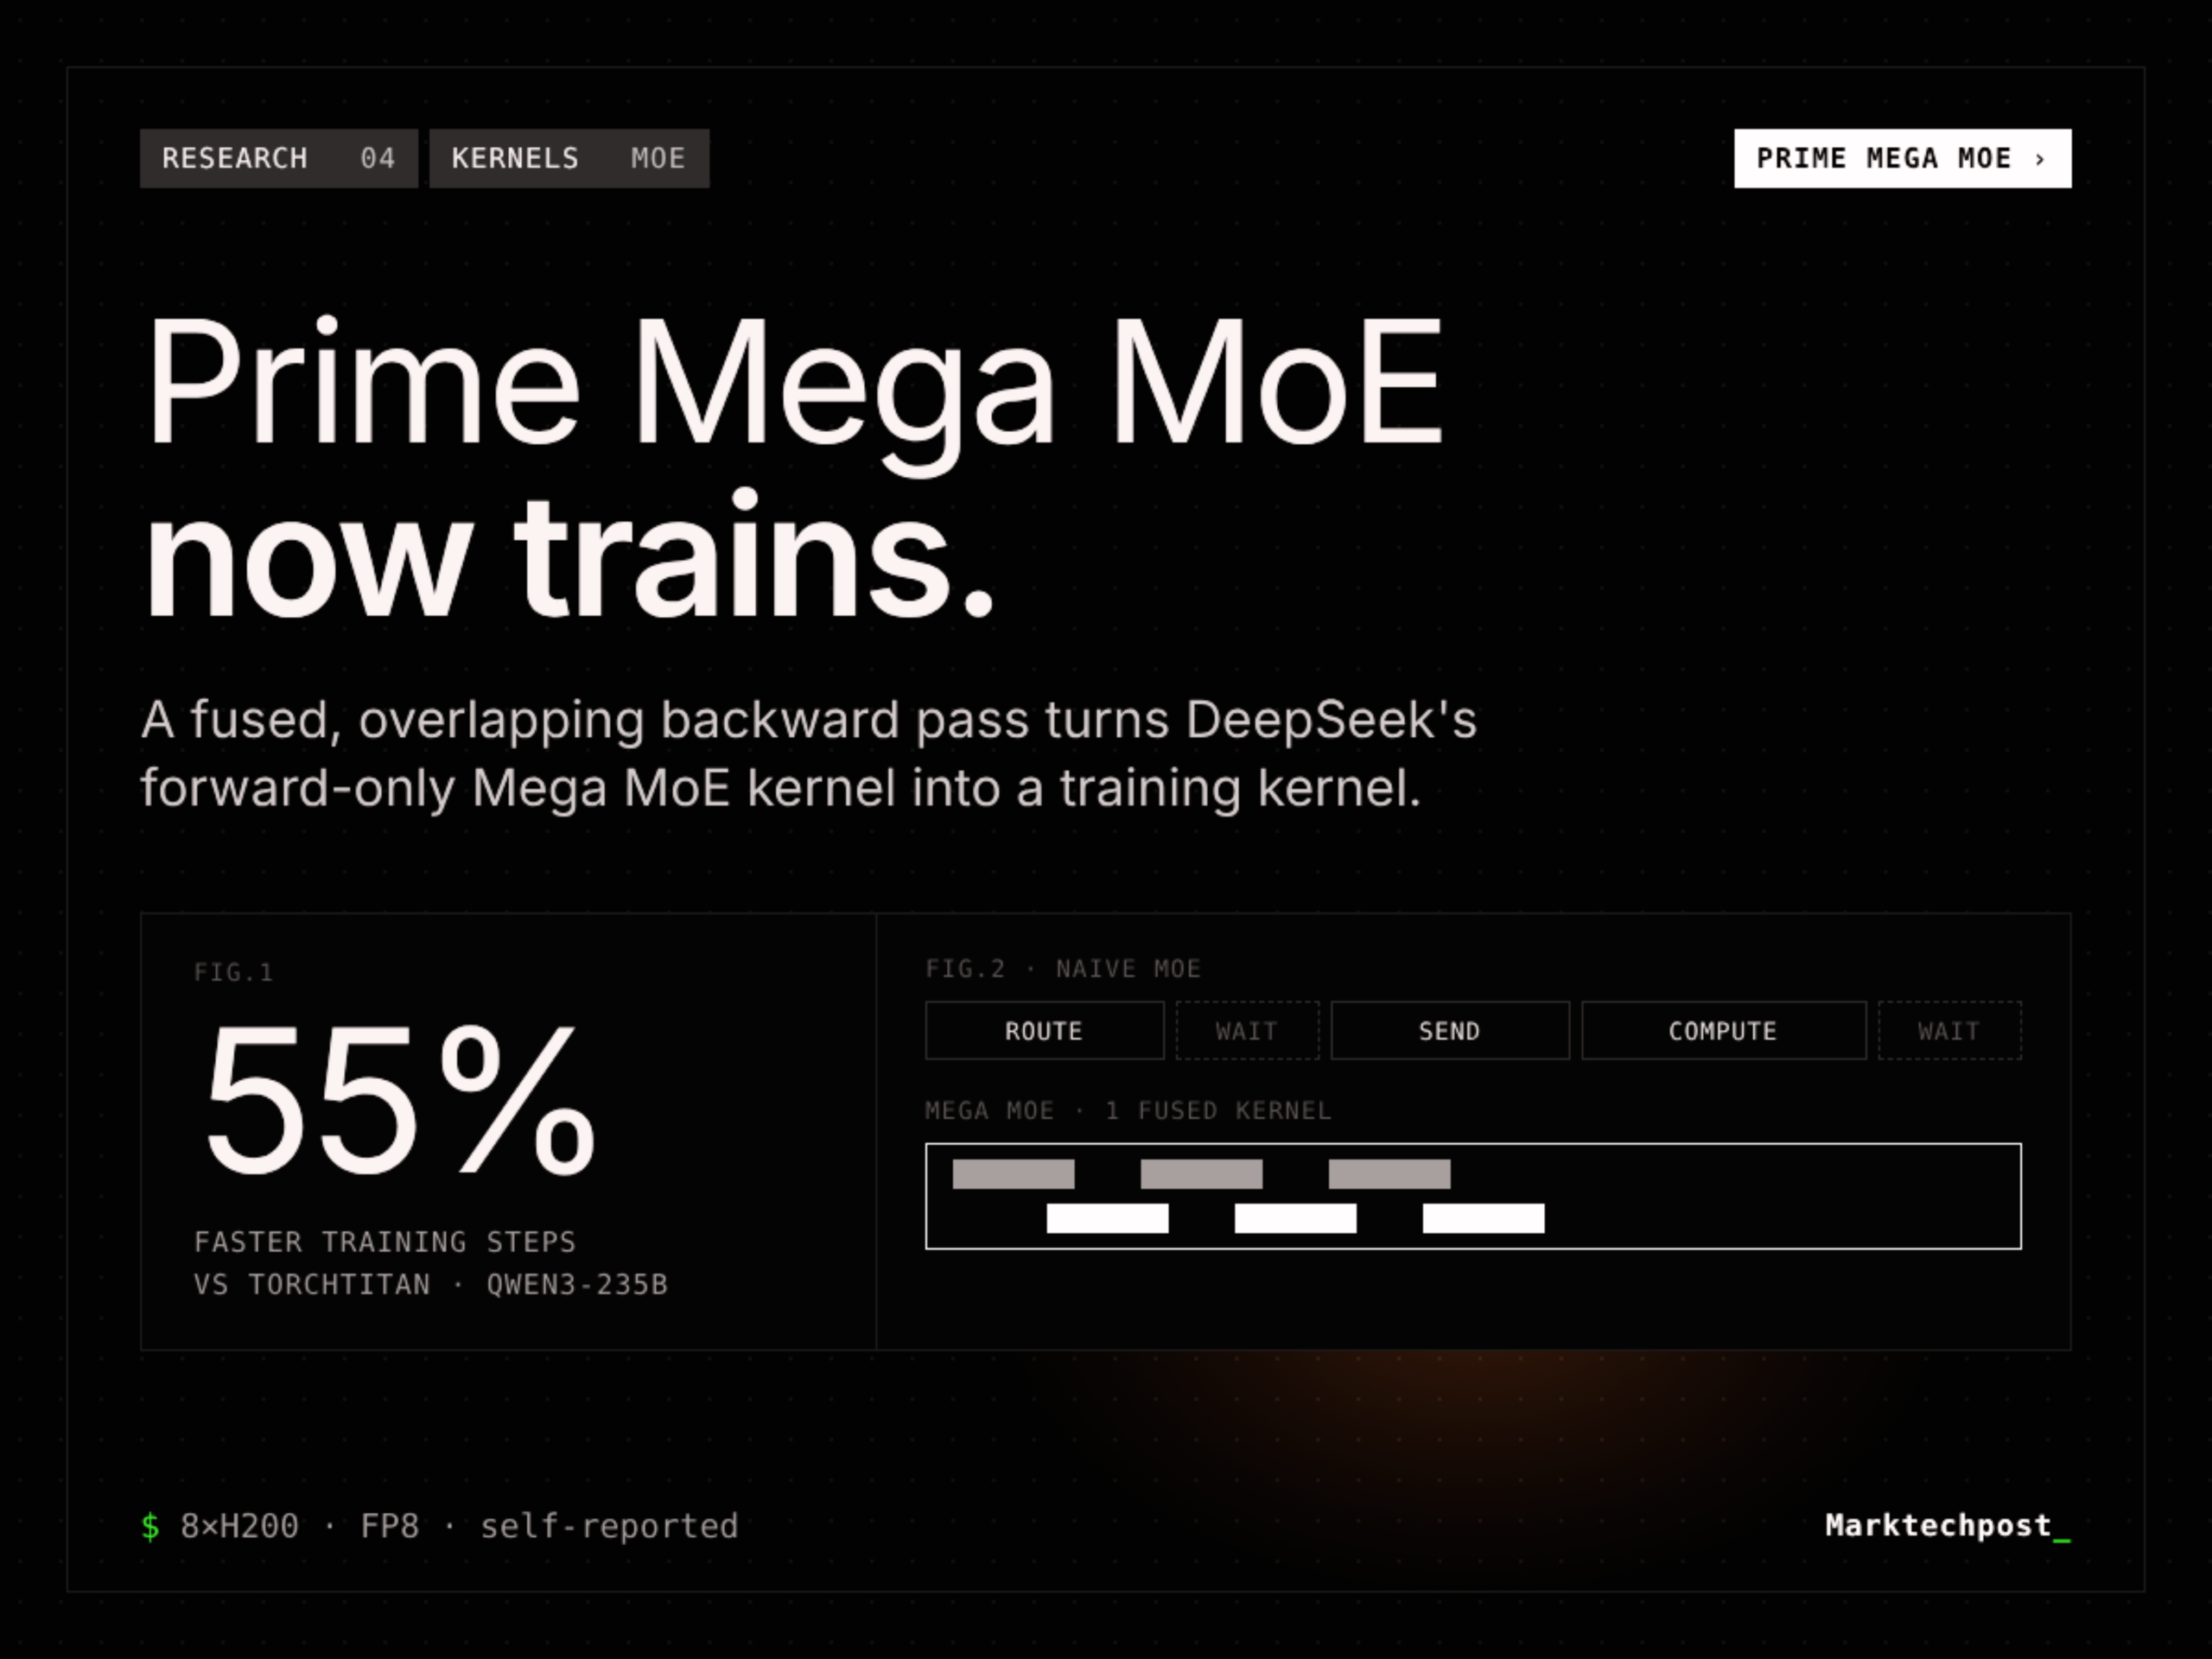
Prime Intellect released Prime Mega MoE, a trainable fused MoE kernel for DeepSeek's architecture, speeding Qwen3 MoE training steps by up to 34% and forward passes 3.11x faster.
Key Takeaways
- Key Highlight:Prime Intellect released Prime Mega MoE, a trainable fused MoE kernel for DeepSeek's architecture, speeding Qwen3 MoE training steps by up to 34% and forward passes 3.11x faster.
- Key Topics:DeepSeek, Qwen, Prime, Intellect
Prime Intellect has released Prime Mega MoE, a backward pass implementation for DeepSeek's fused Mega MoE kernel. This makes the kernel trainable, addressing a gap in open-source MoE training infrastructure.
The kernel is reported to speed up Qwen3 MoE training steps by up to 34% in the prime-rl framework and deliver a 3.11x faster forward pass. These gains target the compute bottlenecks common in mixture-of-experts models.
The release could lower the cost of training large MoE models and improve efficiency for researchers. It also signals continued momentum in open-source AI infrastructure, where kernel-level optimizations are becoming a key differentiator.
This page provides an editorial summary based on publicly available information. It is not a republished article. Use the source link below for the original report.