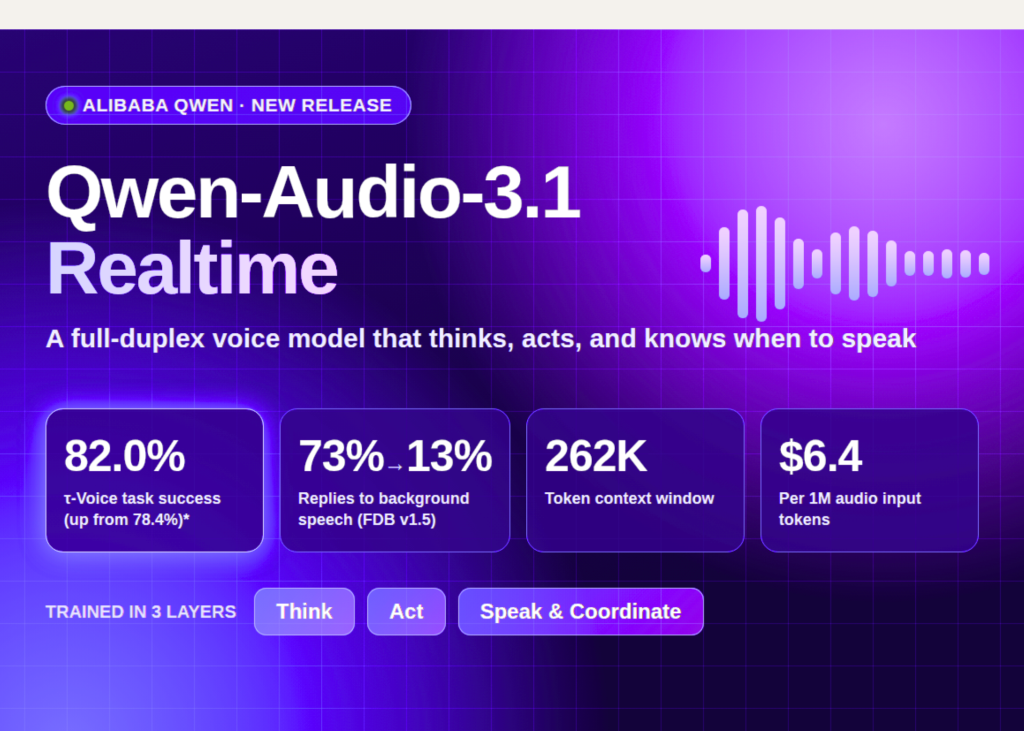
Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak
Alibaba's Qwen team released Qwen-Audio-3.1-Realtime, a full-duplex voice model that can reason, call tools, and manage turn-taking. Task success rose to 82.0% from 78.4%, and false replies to background speech dropped from 73% to 13%.
Key Takeaways
- Key Highlight:Alibaba's Qwen team released Qwen-Audio-3.1-Realtime, a full-duplex voice model that can reason, call tools, and manage turn-taking. Task success rose to 82.0% from 78.4%, and false replies to background speech dropped from 73% to 13%.
- Innovation & Tech:Highlights advancements in Qwen, Alibaba, Releases, demonstrating rapid progress in model capabilities.
- Industry Impact:Reported via MarkTechPost, offering actionable signals for developers and technology leaders.
Alibaba's Qwen team has introduced Qwen-Audio-3.1-Realtime, a full-duplex voice model built for real-time spoken interaction. Unlike conventional speech-to-text pipelines, it is designed to reason, invoke external tools, and decide on its own when it should speak.
Benchmark results shared with the release point to measurable gains. On a τ-Voice adaptation benchmark, task success improved from 78.4% to 82.0%. Perhaps more significantly, the model's tendency to respond to background speech fell from 73% to 13%, suggesting far better selectivity in noisy or multi-speaker settings.
The turn-taking capability is central to the design. Full-duplex models that can listen and talk simultaneously need to distinguish directed speech from ambient noise, and the sharp drop in false triggers indicates progress on that front. This matters for deployment in real-world environments where interruptions and overlapping dialogue are common.
Tool-calling adds an agentic layer, allowing the model to take actions rather than only generate spoken responses. Combined with reasoning, this positions Qwen-Audio-3.1-Realtime closer to voice-based agents that can handle multi-step tasks through conversation.
The model is available now as an API, placing Alibaba among the companies pushing real-time voice agents toward more practical, production-ready use.
This page provides an editorial summary based on publicly available information. It is not a republished article. Use the source link below for the original report.
Industry Insights & Analysis
As artificial intelligence rapidly evolves, breakthroughs surrounding Qwen, Alibaba, Releases, Qwen-Audio-3.1-Realtime are shifting toward scalable, robust real-world implementations.
Driven by both open-source ecosystems and proprietary model architectures, the integration between compute optimization, data engineering, and agentic workflows is accelerating. This development provides a strategic benchmark for upcoming AI tooling and developer workflows.