Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
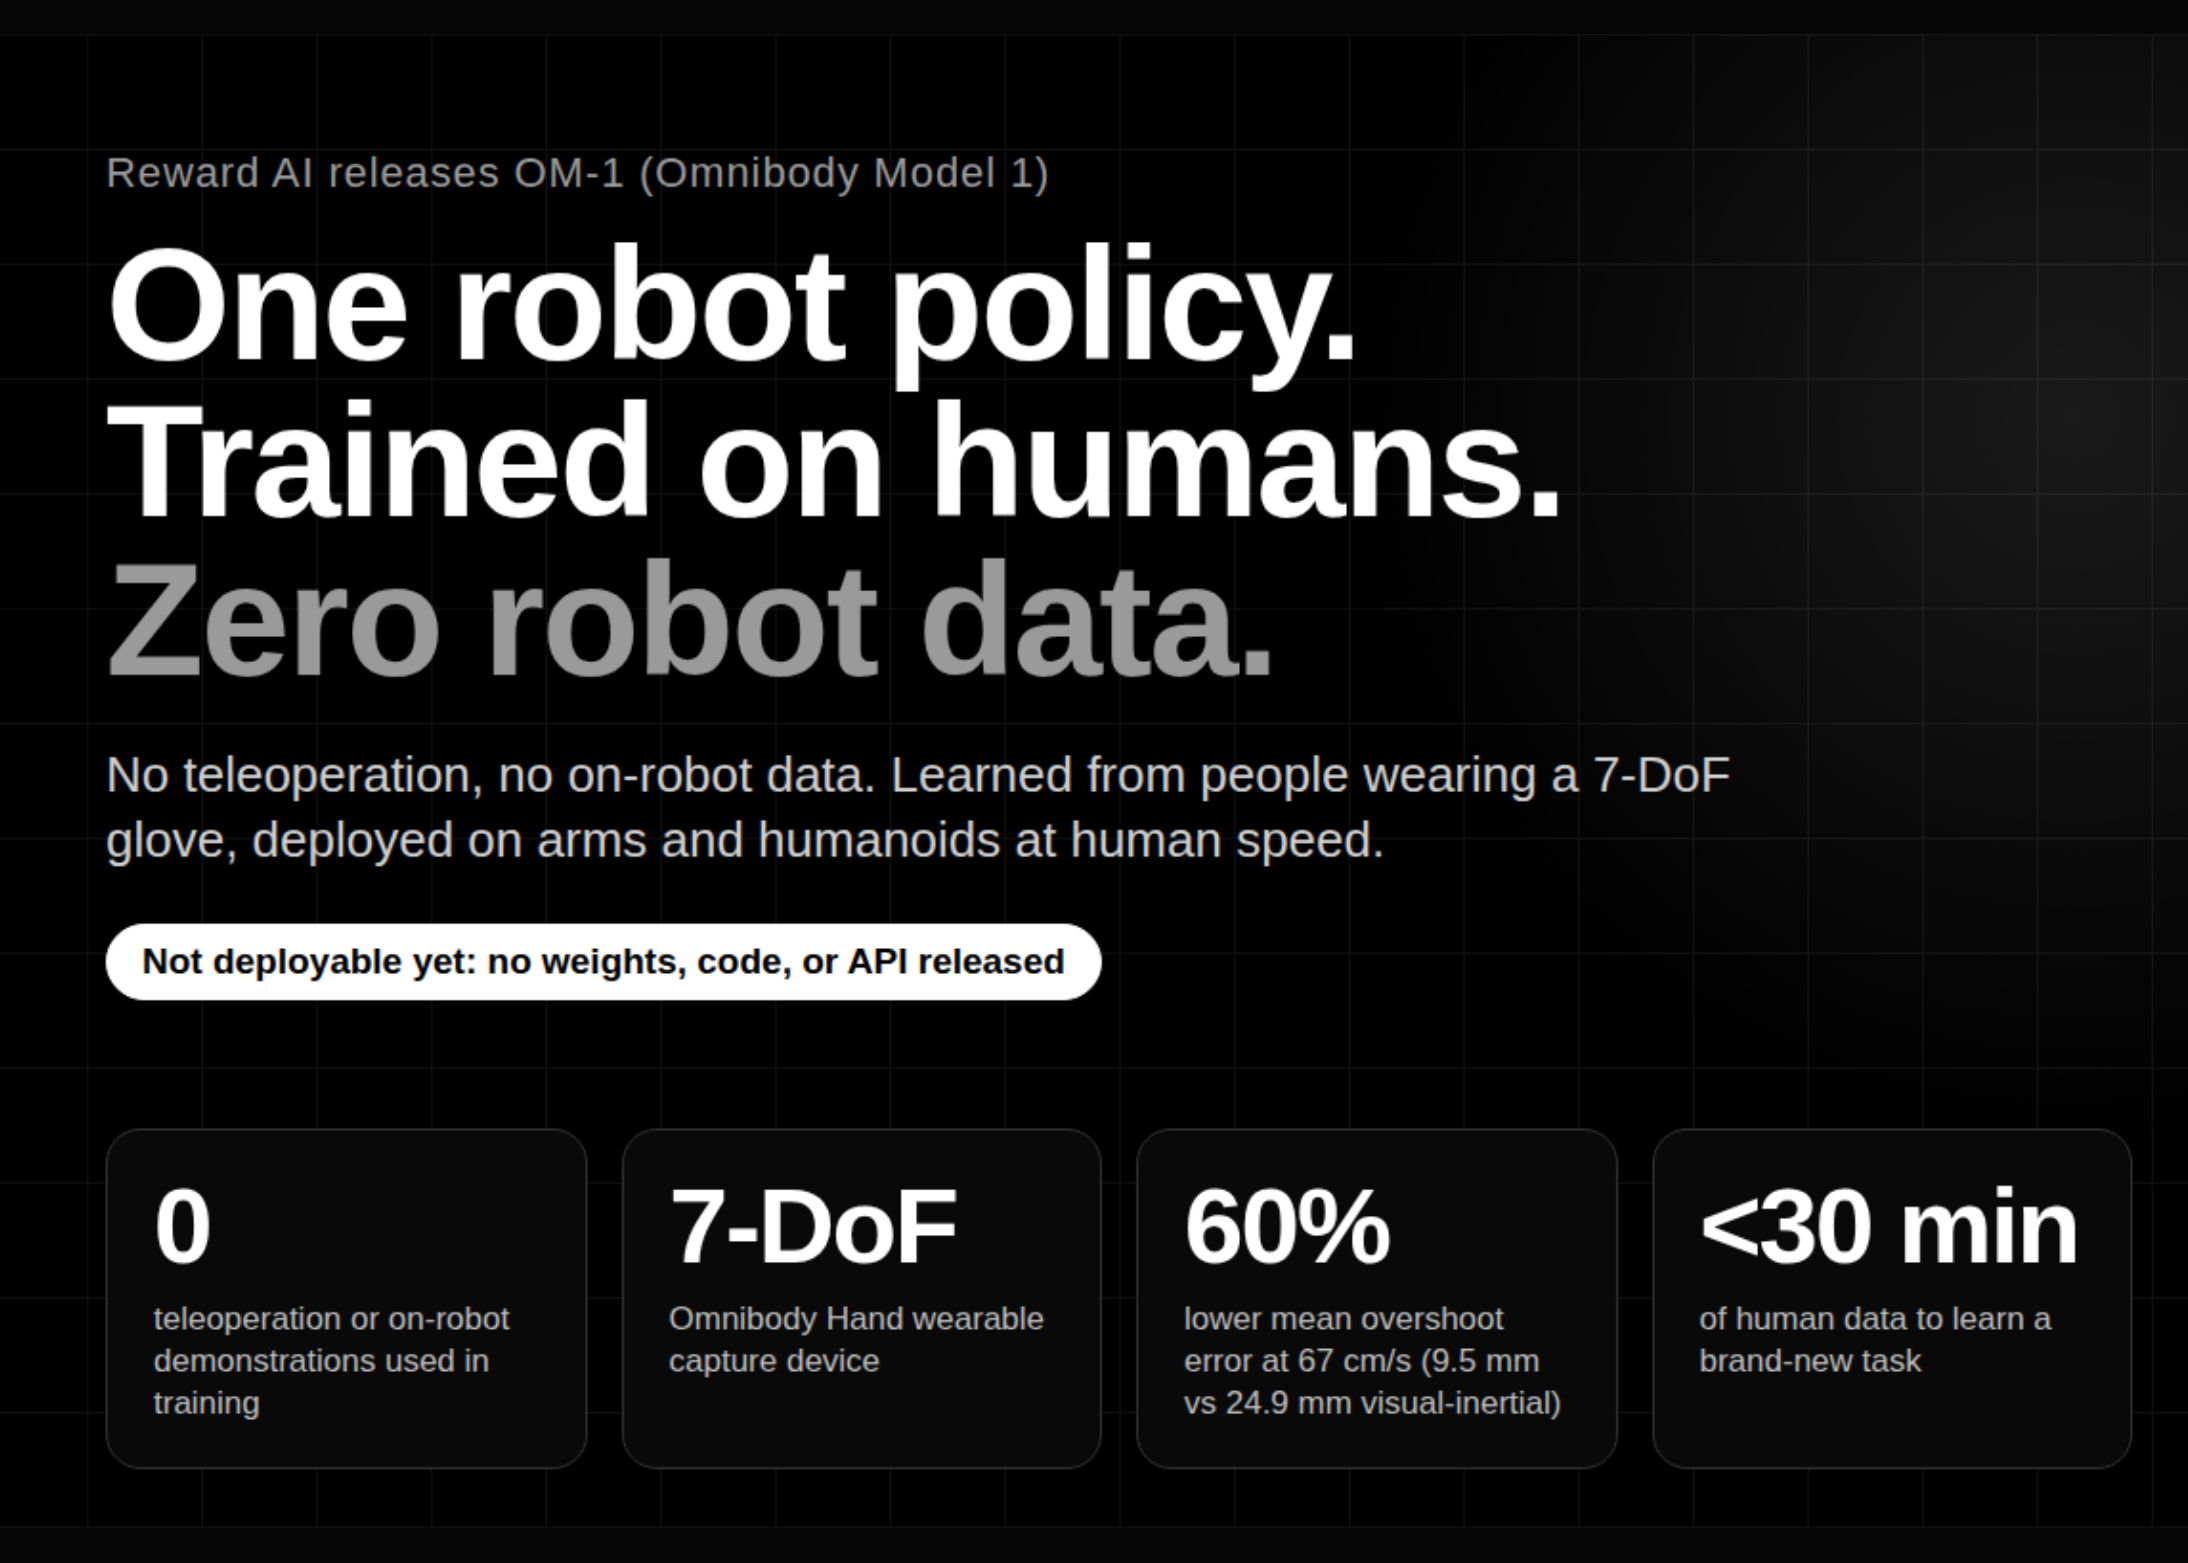
Reward AI released OM-1, a general-purpose manipulation policy trained solely on human demonstrations captured via a 7-DoF wearable glove. It requires no teleoperation or on-robot data and runs on industrial arms and humanoids at human speed.
Key Takeaways
- Key Highlight:Reward AI released OM-1, a general-purpose manipulation policy trained solely on human demonstrations captured via a 7-DoF wearable glove. It requires no teleoperation or on-robot data and runs on industrial arms and humanoids at human speed.
- Innovation & Tech:Highlights advancements in Reward, AI, Releases, demonstrating rapid progress in model capabilities.
- Industry Impact:Reported via MarkTechPost, offering actionable signals for developers and technology leaders.
Reward AI has introduced OM-1 (Omnibody Model 1), a general-purpose robot manipulation policy designed to control both industrial robotic arms and humanoid robots. The system is notable for its data collection method, relying entirely on human demonstrations recorded through a 7-DoF wearable glove.
By eliminating the need for teleoperation or on-robot data collection, OM-1 streamlines the training pipeline for robotic control. This approach could significantly reduce the time and cost associated with gathering diverse training data, which has traditionally been a major bottleneck in robotics development.
The policy reportedly operates at human speed, aiming to translate direct human hand motions into capable robotic manipulation across different hardware platforms. This cross-embodiment capability suggests a path toward more generalizable AI models in physical automation.
If the approach scales effectively, it could accelerate the deployment of capable robots in industrial and humanoid settings by simplifying how manipulation skills are learned and transferred to machines.
This page provides an editorial summary based on publicly available information. It is not a republished article. Use the source link below for the original report.
Industry Insights & Analysis
As artificial intelligence rapidly evolves, breakthroughs surrounding Reward, AI, Releases, OM-1 are shifting toward scalable, robust real-world implementations.
Driven by both open-source ecosystems and proprietary model architectures, the integration between compute optimization, data engineering, and agentic workflows is accelerating. This development provides a strategic benchmark for upcoming AI tooling and developer workflows.